Chuyue Wang
LLM inference & agents. Penn '29.
I work on LLM inference at Penn's Distributed Systems Lab and contribute upstream to SGLang and vLLM.
steven’s thinking
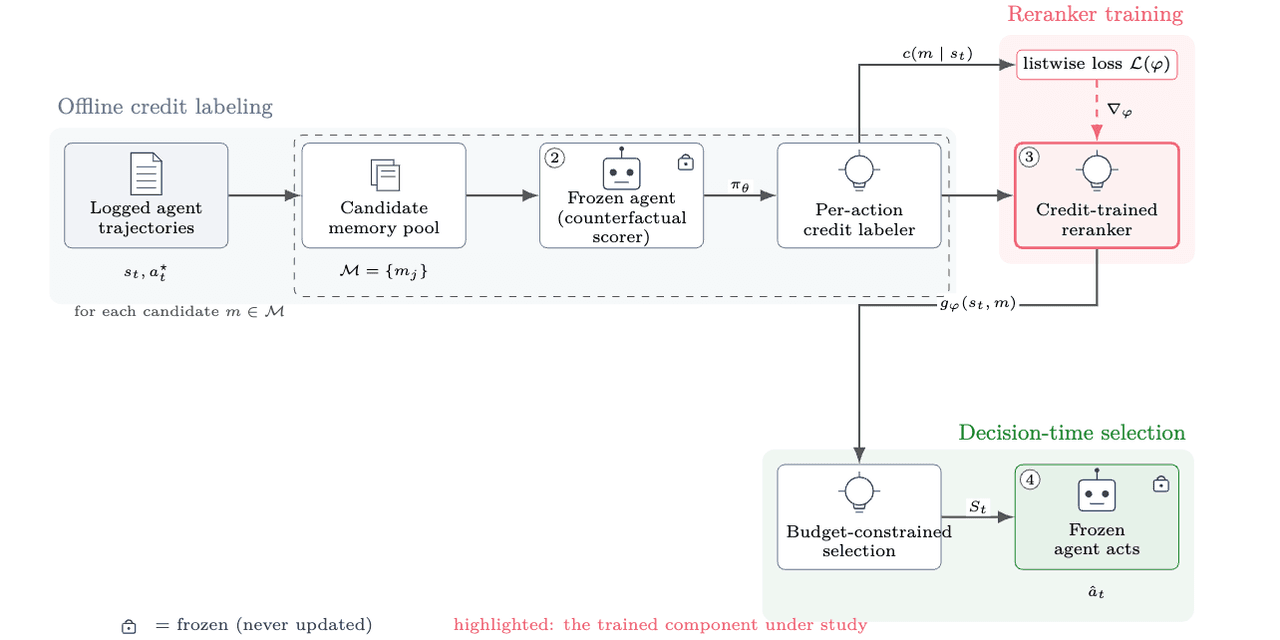
I work on LLM inference and agent systems. Right now that means sparse attention that cuts KV-cache reads without losing accuracy, and a memory layer that lets an agent reuse what it has already worked out.
The hard part is rarely the idea itself. It is the latency budget, stale state, and instructions that only half specify the job.
Internships and research, most recent first.
Internships
Software Engineering Intern
Kosa turns a company's email into structured deal updates. I built the tenant-scoped, idempotent commit layer behind those updates, and shipped MiniKosa, a macOS copilot with on-device transcription.
- TypeScript
- Electron
- Whisper
- FTS5
Research Engineering Intern
Co-authored Traj2Mem, a procedural memory that lets an agent reuse strategies from its past trajectories without retraining, and owned its retrieval and evaluation pipelines. The work is now part of the institute's technology-transfer portfolio, which works with ByteDance, OPPO and other companies.
- Python
- Agent Memory
- Retrieval
Agent Engineering Intern
Built a record-and-replay harness that made the Engine agents' tests deterministic, along with the assertion pipelines that judge each replay.
- Python
- Redis
- PostgreSQL
- WebArena
Founding Engineer
An AI networking agent that runs inside iMessage. I built the backend, including LangGraph orchestration, hybrid vector and graph matching, and durable queues with retries.
- LangGraph
- FastAPI
- Redis
Derivatives Valuation Intern
Implemented Gaussian Heath–Jarrow–Morton models for swaption pricing and rewrote the desk's daily exotic-equity valuation, cutting a run from two days to four hours.
- Python
- Numerical Methods
Research
Research Engineer, advised by Prof. Bingxin Zhao
Built a post-cutoff benchmark for LLM paper review, which tests whether a model can evaluate a paper it has never seen. The results showed that a model's prior knowledge of an author can bias its judgment more than the paper's own content.
- Python
- LLM Eval
- Benchmarks
Research Assistant, advised by Prof. Vincent Liu
Wrote the CUDA/C++ scoring kernels for BrowserSparseAttention, which page the KV cache by what each query needs, and served them through SGLang on FP8.
Co-developed FullStackArena, a browser-agent benchmark across six stateful web apps, under review at NeurIPS 2026.
- CUDA/C++
- FP8
- SGLang
- FlashInfer
Research Software Engineer, advised by Prof. Hsiao-Wen Cheng
Built and deployed yijianzhi.net, a trilingual database of 2,745 Song-dynasty stories used by 120+ scholars. Selected for the 2026 GPASC Undergraduate Summer Grant, one of two projects from 100+ submissions.
- Flask
- PostgreSQL
- NLP
Under submission. Titles are withheld where double-blind review applies.
A mysterious paper on Agent Memory Retrieval
Chuyue Wang, …
Title and co-authors withheld under double-blind review.
A mysterious paper on 3D Gaussian Splatting and Reinforcement Learning
…, Chuyue Wang*, …
*Equal contribution. Title and co-authors withheld under double-blind review.
FullStackArena: Evaluating Browser Agents in Dynamic and Temporally Evolving Full-Stack Environments
Jiaheng Lu, Xian Wang, Chuyue Wang, Shrishti Roy, Colin Zhao, Sidharth Sankhe, Xuting Liu, Spyros Pavlatos, Linh Phan, Vincent Liu
 Open the paper (PDF)
Personal projects, all open source.
Visit SILKern. (opens in new tab)
Sparse-index localization kernels for context-parallel decode: deterministic, allocation-free, CUDA-graph-safe.

Hand-written CUDA kernels that localize sparse KV indices under context-parallel decode. They are deterministic, allocation-free, and CUDA-graph-safe, so they run inside a captured decode graph without touching the allocator.
- CUDA
- Python
Visit Township (opens in new tab)
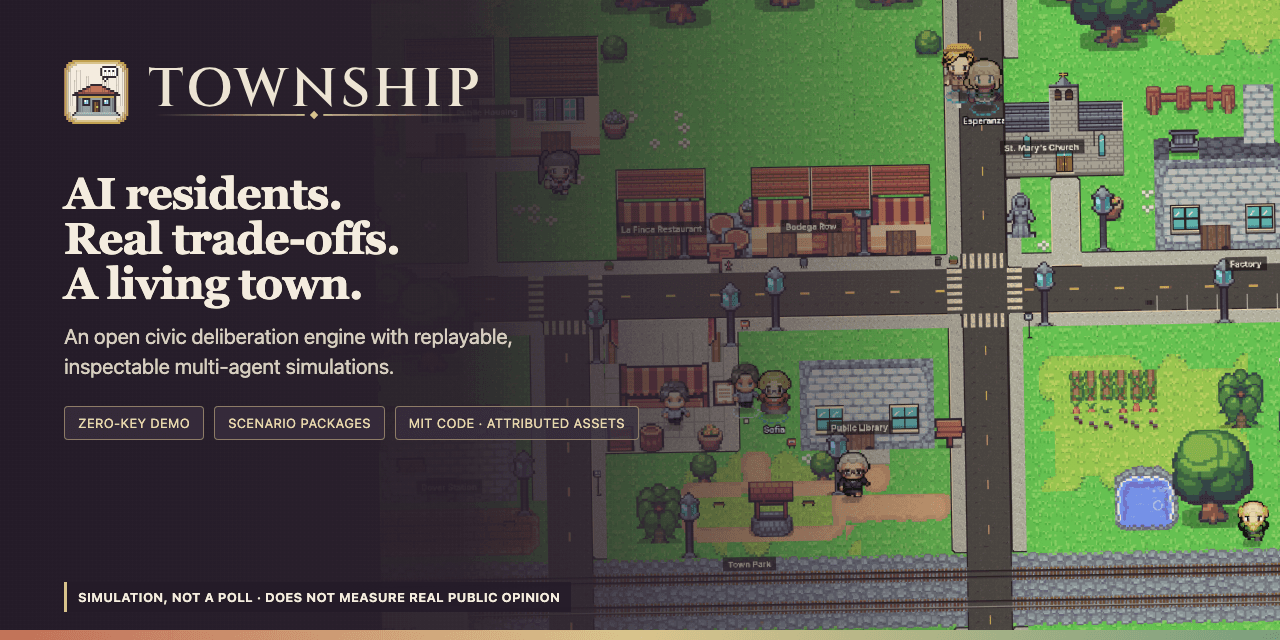
AI residents deliberate civic questions in a pixel town. A replayable, scenario-first simulation engine.
Visit AutoPaperLab (opens in new tab)
Turns research briefs into auditable paper packages, with verified citations and reproducible experiments.
A research-to-paper pipeline built on one rule: every citation, number, and result has to trace back to something real, or the draft does not ship.
- Python
- LLM Agents
Most of what I build runs on SGLang and vLLM. When something breaks, I fix it upstream, so the next person never hits it.
SGLangVisit SGLang on GitHub (opens in new tab)
Contributor to sgl-eval and SpecForge
sgl-eval is SGLang's accuracy evaluation harness. My patches fix chat-template preset precedence, pin MMLU to a verified archive, and reject duplicate example IDs before a run starts. In SpecForge, SGLang's toolkit for training speculative-decoding models, fixed a race in how the runtime publishes its consumer quantum and made its HF exports honor explicit vocabulary mappings. Two fixes to SGLang itself, on the FlashInfer CUDA-graph decode path and the Responses API, are in review.
- Python
- Eval Harness
vLLMVisit vLLM on GitHub (opens in new tab)
Contributor to vLLM, its FlashAttention fork, vllm-metal and agentic-api
In vLLM, synced the attention backend with upstream FlashAttention and brought the project's FlashAttention fork up to date. In vllm-metal, vLLM's Apple Silicon backend, fixed paged attention for EXAONE 4.0, StableLM and Granite 4.0, BF16 LoRA loading in MLX, token logprobs, Whisper and Qwen3-ASR decoding, embedding-model support, and offline GGUF loading. In agentic-api, the stateful layer for agent applications, fixed Responses configuration forwarding, streamed-reasoning reconciliation, stream termination, proxy-header handling, and startup readiness.
- vllm1 merged
- flash-attention33 merged (opens in new tab)
- vllm-metal17 merged
- agentic-api16 merged
- Python
- CUDA
- Rust
- MLX
Everything else.

Chuyue Wang
Philadelphia · wangcy07@sas.upenn.edu
- GPASC Undergraduate Summer Grant — one of two projects selected from 100+ submissions2026
- 1st Place, Democratic Governance — Anthropic × University of Pennsylvania AI Hackathon2026
- 1st Place — Avalanche Team 1 × Foundry Start-Up in a Weekend, Hybrid Intelligence Track2025
- Finalist (Top 11 of 967) — High School Mathematical Contest in Modeling, COMAP2024
- National Gold Medal — Physics Bowl, AAPT2023